Companies that maintain complex software systems (fintech platforms, healthcare applications, SaaS products, or ongoing legacy modernization projects) share a common set of challenges. Each new release risks breaking functionality that once worked when seemingly unrelated code paths are touched. Deployments become stressful for engineers and worrisome for stakeholders who depend on stable, predictable releases. Development teams want to make updates faster without sacrificing reliability, and defects must be detected early in the lifecycle, before customers are affected. Achieving these goals requires automated regression testing.
What Is Regression Testing
CEOs, COOs, CTOs, VPs and Heads of Engineering or Software Delivery don't want the definition of what regression testing in software testing is.
They need to understand whether the professionals who claim to be experts in regression testing have real experience in this kind of testing. That experience has to be comprehensive enough on systems like theirs. Only then can they believe that handing over the execution of this critical part of their delivery process will help them regain control over their evolving application behavior.
From the point of view of technical and non-technical stakeholders, the definition of regression testing is less important than the final goal of such activity.
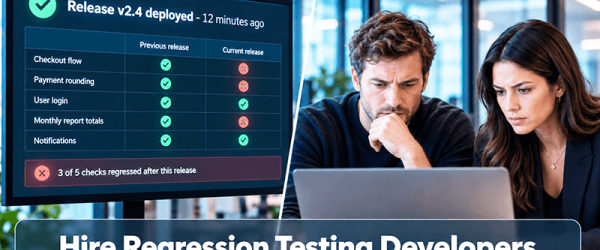
One change could inadvertently affect the quality of business features of the software their clients are already paying for.
After the implementation of each change, update, new feature and each release as a whole, the existing functionality of their platform must remain unaffected, critical workflows stay fully functional, none of the old features break, new bugs are not introduced and everything still works.
It's not smoke testing, which checks if the core functions work at all, and neither is it the testing of a new feature they build for their clients, which checks whether all its details work as specified.
Regression testing in its full form retests all features of the app, not just the core ones, focusing above all on the old features.
To continuously find errors, only an automated process can check the product's behaviors every time developers commit new code to the codebase, and repeat full test cycles on a schedule plus after each deployment.
Automated testing scenarios executed periodically, for example, several hundred automated tests weekly, every day, twice a day or even more often, allow stakeholders to see new regression issues almost immediately.
Automated regression tests at the unit, API and end-to-end levels before delivery to customers catch regressions before release, reduce the volume of bugs and regressions reaching production and also cut down manual effort in repetitive testing tasks.
Belitsoft provides a software testing and QA team that strengthens regression coverage where it matters most - so rapid updates don't reintroduce old bugs or break core workflows.
Why Regression Testing Is Important
Regression testing is a quality assurance practice that allows a team to add, fix, or tune code without sacrificing stability. After every change - whether a bug fix, new feature, performance tweak, or platform or configuration update - the already built application is retested methodically. The run serves two goals: retesting confirms that the new change behaves as intended, regression testing verifies that no existing feature has been harmed. By running this suite, engineers check for unexpected faults ("regressions") that may be introduced anywhere in the product as side effects of the latest work.
The primary role of regression testing is to confirm that new code changes leave existing features untouched. By rerunning selected tests after each update, the process uncovers any unintended defects that modifications may introduce. This protects stability across the software life cycle, and lowers business risk. Organizations that apply a regression testing strategy deliver more reliable, higher quality products.
Modern software is full of hidden dependencies. A single application can knit together thousands of classes, APIs, and configuration flags, so large, complex codebases inevitably develop intricate interconnections. Because of that tight coupling, even a modest, well-intentioned edit can ripple outward in unexpected ways.
Regression issues are common: in large codebases such as the Linux kernel and Google Chromium, studies attribute roughly half of all defects to unintended side effects of change. By tying test depth to change impact, maintaining strong collaboration between development and QA, and cycling quickly through detection, correction, and retest, organizations keep that share under control and protect release schedules.
Regression testing keeps critical systems stable and reliable. A regular automated regression suite run gives teams assurance that updates do not destabilize the application. It checks that existing features remain intact even as internal dependencies deepen. Otherwise, one module's improvement could unpredictably undermine another, and side effects stay hidden until they disrupt production. By rerunning automated tests after each change, QA teams catch those side effects early, avoid defect spread, and cut the time spent on difficult debugging later. Without systematic regression, there is no dependable guarantee of stability.
Hidden dependencies carry financial implications. Regression testing catches ripple effects early, and early detection saves both cost and disruption: fixing a defect minutes after introduction is far cheaper than doing so late in the cycle or firefighting in production. Quality is built in from the outset rather than added on later, so a strong regression practice delivers long-term savings in both cost and time. Regression testing is therefore a strategic investment, not a discretionary expense.
In the most critical domains - healthcare, finance, transportation - an inadequate regression process can endanger human safety itself.
Our software testing and QA experts align regression testing with your delivery process combining strategy, automation, and domain expertise to keep releases stable and defects contained, even during rapid or frequent deployments.
When to Do Regression Testing
Regression testing begins the moment a codebase changes. A new feature, an enhancement, a bug fix, an integration with another system, a move to a new platform, a refactor or optimization, even a simple configuration tweak - all trigger the need to verify that existing behavior still works. The size of the change and the importance of the affected functions dictate how often the regression suite should run and how deep it should probe.
Regression testing in Agile is usually incorporated into every sprint. If the team uses test automation, regression checks become a natural part of development, boosting speed and reliability. Team structure and experience influence when automated tests are run. Pipeline execution varies: some run on each commit, others at sprint, release, urgent fix or major refactor intervals. In many CI/CD setups, automated regression tests run on selected builds and provide feedback within minutes. If any test fails, the pipeline can stop the code from moving forward. The same automated loop keeps development and operations aligned in a DevOps workflow.
Set frequency rules that adapt to risk: for automated tests, run the high-priority subset on every commit, the full suite nightly, and an extended suite - including low-risk paths - before major releases. Where possible, trigger only the tests that cover the changed code paths to save time.
How to Build a Regression Testing Strategy
An effective test strategy combines both perspectives: it verifies "what's new" through retesting and functional checks, and safeguards "what else" through a solid, regularly executed regression suite.
Start by defining a clear purpose for regression testing: protect existing business-critical behavior every time the code changes. Then rank the parts of the product according to business and technical risk, and focus regression effort where a fault would hurt the most.
Translate that purpose into measurable objectives - zero escaped regressions in high-risk areas, fast feedback that fits within the team's "definition of done," and predictable cycle times that never block a release.
Create explicit entry criteria (build succeeds, key environments are available, required test data is loaded) and exit criteria (all critical tests pass, defects triaged, flakiness below an agreed threshold).
How to Do Regression Testing Step by Step
The team first identifies the exact change set, recorded in version control such as Git. Developers and testers then conduct an impact analysis together, mapping out which modules, data flows, or performance characteristics might feel the ripple. That analysis drives how to select test cases for regression testing and prioritize them: critical customer paths, areas with a history of defects, heavily used features, and complex components rise to the top of the queue. A production-like, isolated environment is set up to ensure clean results, and the chosen tests are executed. The team reviews the output, logs any regressions, and pushes fixes. Once the fixes land, the same tests run again - an iterative loop that repeats until all essential checks pass.
Design test cases as small, modular building blocks that target a single outcome and share common setup and utilities.
Tag each case with metadata such as risk level, business impact, and execution cost so the pipeline can choose the right blend for any build.
Review tags and priorities after each release to be sure they still reflect reality, and remove redundant or obsolete tests to keep the suite lean. Back every decision with impact-analysis reports that show exactly which components changed and which tests matter for each build.
Reserve manual regression testing and exploratory sessions for complex, low-predictability risks where human insight is irreplaceable.
Regression Test Suite Management
A regression test suite begins with a small set of tests that protect the features most important to customers and revenue. Every test in the suite should defend a business-critical function, a high-risk integration, or a part of the code that changes often.
Tests also need variety. Quick unit tests catch simple logic errors, integration tests confirm that services talk to one another correctly, and end-to-end tests walk through real customer scenarios. Together, they give leadership confidence that new releases will not break essential workflows.
As the product grows, the suite expands in step with it. Engineers add tests when new features appear, update them when existing features change, and remove them when functionality is retired. Flaky tests - those that fail unpredictably - are fixed or discarded immediately, because false alarms waste engineering time. Regular reviews keep coverage aligned with current business priorities, and version control records every change.
How to Improve Regression Testing
Schedule maintenance alongside feature work: refactor flaky locators, update data sets, and archive tests that no longer add value. Track flaky tests with the same discipline you apply to product defects: isolate them quickly, find the root cause, and either fix or delete them to preserve trust in the results.
Track key metrics - defect detection rate, total execution time, coverage versus risk, and the percentage of flaky tests - and review them in regular retrospectives.
Use the data to tune priorities, expand coverage where gaps appear, and slim down areas that no longer matter.
Treat regression testing as a software project and the test suite as living code: apply clear objectives, modular design, and continuous improvement, monitor it, refactor it, and remove duplication to keep it useful over time.
Finally, make quality everyone's job. Share dashboards that expose test results in real time, involve developers in fixing failing scripts, invite product owners to flag rising risks, and triage failures together.
How to Automate Regression Testing
Because regression tests repeat the same checks, they are well-suited for automated regression testing. This is especially true in environments with frequent changes: automated test suites can rerun after each update without manual effort, enabling teams to swiftly and reliably verify software functionality. Automation brings speed, consistency, broader coverage, reusable scripts, rapid feedback, and lower long-term cost, and it is ideal for early issue detection in fast-paced development cycles. However, automation is not suited for tests that are subjective or cover highly volatile areas.
Automate the scenarios that bring the highest return - stable paths that change rarely, have clear pass/fail oracles, and save the most manual effort. Write scripts so they are easy to read, easy to update, and able to "self-heal" when minor UI changes occur.
Hook these scripts into the CI/CD pipeline so they run unattended, in parallel, and close to the code. Use cloud resources to spin up as many test environments as needed and drop them when finished.
Widely used regression testing tools include Selenium, Appium, JUnit, TestNG, Cypress, Playwright, TestComplete, Katalon, Ranorex, and CI orchestrators such as Jenkins, GitLab CI, GitHub Actions, and Azure DevOps. These require upfront investment, specialist skills, and ongoing script maintenance.
Automation promises relief, yet it introduces its own complexities: framework installation, unstable XPaths or CSS selectors, and the need for engineers who can debug the harness as readily as the application code. These overheads are the price of the consistency and round-the-clock execution that manual runs simply cannot match.
Realistic, repeatable test data adds another layer of complexity - keeping databases, mocks, and external integrations in a known state demands disciplined version control.
Regression Testing Future Trends
Regression testing is becoming smarter and more proactive. AI and machine learning models already analyze past results, code changes, and production incidents to pick only the tests that matter most, rank them by risk, and heal broken locators automatically. The next step is predicting where the next defect is likely to surface.
The practice is also shifting in both directions along the delivery pipeline. "Shift-left" efforts are pushing more regression checks into developer workflows - unit-level suites that run with every local build so problems are caught before code ever reaches the main branch. At the same time, "shift-right" techniques such as canary releases, real-user monitoring, and anomaly-detection dashboards watch live traffic for signs of post-release regressions.
UI quality gets extra protection from automated visual-regression tools that compare screenshots or DOM snapshots to baseline images and flag unintended layout or style changes. Functional suites are starting to capture lightweight performance indicators (response time, memory spikes) so that a passing feature test can still fail if it degrades user experience.
Managing realistic, compliant test data - especially in regulated domains - remains a challenge, and new on-demand data-management platforms are emerging to mask, generate, or subset data sets automatically. Toolchains are evolving as well: frameworks now support micro-services, containerized environments, multi-device matrices, and globally distributed teams working in parallel.
Taken together, these trends do not replace regression testing - they make it more intelligent, better integrated, and able to keep pace with modern development.
How Belitsoft Can Help
Belitsoft is the regression testing partner for teams that ship fast but can't afford mistakes.
We provide QA engineers, automation developers, and test architects to build scalable regression suites, integrate with your CI/CD flows, catch defects before users do, and protect your product as it evolves. Whether you're launching new features weekly or migrating to the cloud, Belitsoft ensures that what worked yesterday still works tomorrow.
Automated Regression Testing
We design and maintain regression suites that cover units, integrations, user interfaces, and performance. Stable automation frameworks such as Selenium, Cypress, and Playwright run inside your CI/CD pipeline, so each build validates existing functionality without manual effort.
Regression Strategy and QA Architecture
Our architects define clear testing objectives, apply risk-based prioritization, and map critical regression paths. Fixes for past defects are preserved as permanent tests, and we separate the scope for new code from reused modules to keep regression debt under control.
Dedicated Regression QA Teams
Specialized engineers handle test creation, maintenance, and continuous execution. They diagnose flaky tests, improve stability, and maintain full traceability to business requirements, allowing your in-house developers to remain focused on feature delivery.
Custom Test Automation Development
We build scalable automation solutions tailored to your technology stack, whether legacy monoliths, microservices, or complex front-end frameworks, and integrate functional tests with performance and security checks. The result is faster release cycles, cleaner code, and fewer post-deploy hotfixes.
Post-Integration Stability Testing
After configuration changes, integrations, or environment updates such as operating system patches or database migrations, we run targeted regression passes to confirm that the system remains stable through continuous change.
Our offshore QA teams reduce regression workload and catch critical defects early, so your team avoids late-cycle disruptions and delivers updates on schedule. With deep experience across industries and technologies, we help companies lower testing overhead, speed up delivery, and prevent costly production issues with savings of up to 40% on quality assurance costs. Start your QA collaboration!
Regression Testing FAQ
What does regression testing mean?
The meaning of regression testing in software development is simple. Each time developers fix a bug, add a feature, or update a library, hidden side effects can appear. To catch them, the QA team should rerun its functional and non-functional tests after every change to check if earlier behavior still matches the specification. Regression testing helps keep existing features stable after code changes. The faster and more often a codebase changes, the higher the chance of accidental breakage, and the greater the need for systematic regression testing. Regression test results help preserve product integrity as the software evolves.
Why is it called regression testing?
The term "regression" itself means a step backward. In statistics, Galton used it to describe values sliding back toward an average. In software, it signals a move from "working" to "broken". Continuous regression testing prevents that slide and keeps released behavior intact as the system evolves.
What is the ISTQB and IEEE definition of regression testing?
The ISTQB describes it as retesting the program after the software or its environment is modified, to ensure no defects appear or surface in untouched areas. The IEEE provides a similar definition, with one refinement: it describes regression testing as selective retesting. That raises the "selective-retest" question - how to pick a test subset that is both fast and reliable.
What is the purpose of regression testing?
Regression testing is explicitly designed to avert any step back, acting as a safety net that preserves the application's overall integrity. Regression tests complement unit and feature tests. While those validate the new code paths, regression tests defend everything else, ensuring that unchanged areas remain unaffected. This embodies the conservative "first, do no harm" principle, counterbalancing innovation so quality never degrades.
Recognizing this fragility forces us to adopt an organized, repeatable reverification. That is regression testing. Software evolves continuously, and sustained quality is unattainable without a mechanism that proves every change leaves yesterday's stable behavior intact.
What are the main objectives of regression testing?
A solid regression testing strategy starts with clear, measurable objectives.
Objective 1 - Protect existing functionality. Every enhancement, patch, refactor, or configuration change is retested not only in isolation but also for possible systemwide ripple effects. The foremost goal is to prove that the new code has not weakened any feature that was already working.
Objective 2 - Keep old bugs from coming back. When a defect is fixed, the test that proved the fix stays in the suite permanently. Each new cycle reruns that test to verify the fix still holds, because later changes can quietly reopen earlier issues. These targeted checks ensure "zombie" bugs stay buried.
Objective 3 - Preserve compatibility after integrations and updates. Modern systems depend on tightly linked modules and services. Whenever a new module is integrated - or an existing one is updated - regression tests confirm there is no collateral damage. Adding a payment gateway, for example, must not disrupt accounts, orders, or reporting. The same suite runs after performance tuning, after linking the product to external systems, and whenever the runtime environment changes, proving the software stays robust under new conditions.
These objectives form a proactive risk management stance: systematic checks stop defects before they escape to production.
What are the benefits of regression testing?
Regression testing delivers clear, measurable gains across engineering, product, and business dimensions.
Faster Development. Automated suites provide immediate green or red results on every commit, so defects are detected while the code change is still small. This early feedback fuels faster development velocity, prevents expensive rework, and keeps continuous integration pipelines flowing without the long bug-fix phases that slow teams. When most tests are automated, regression testing stops being a bottleneck and becomes an enabler of fast development cycles. As each build passes, teams gain confidence that new code will not break existing behavior, which accelerates iteration and shortens release cycles.
Quality Improvement. Rerunning functional, integration, performance, and other nonfunctional checks verifies that the system remains stable, meets user requirements, and performs reliably after optimizations. Consistent early detection of regressions avoids wasted diagnostic effort and reduces the business impact of defects. Verified critical functionality lowers deployment risk and supports predictable releases, which are essential in modern Agile, DevOps, and CI/CD environments.
Financial benefits. Lower defect-removal cost, faster time to market, and higher customer satisfaction translate into clear return on investment, stronger competitive position, and improved brand loyalty.
Better engineering culture. Regular automated runs reinforce collective responsibility for quality, give each developer actionable feedback tied to their change, and encourage mindful, modular design. The growing suite records past failures, codifies critical knowledge about failure modes, and prevents recurrence of previously fixed bugs even as the system and team evolve. Well-named tests act as executable documentation and speed onboarding while consolidated unit, integration, and functional coverage preserve system knowledge.
Automation. It removes repetitive manual work, reduces human error, releases testers for exploratory activities, and accelerates releases. Modern tools - commercial and open source - make large-scale automation accessible, especially for stable areas of code.
Done well, regression testing transforms a perceived burden into a strategic asset, but the payoff requires planning, data-driven maintenance, and sound management practices. Suites must remain maintainable and applications must expose stable interfaces. Otherwise, brittle or flaky tests limit value and often signal problems in the test design or the application interfaces. When these prerequisites are met, regression testing forms a virtuous quality cycle. Automated feedback drives better design, reliable tests sustain rapid delivery, and the organization consistently ships high-quality software with lower cost and risk.
Why do businesses rely on regression testing?
The stakes are commercial as well as technical. Businesses rely on predictable software behavior, and regression testing underpins that dependability. Ongoing verification is essential for long-term stability, allowing teams to move quickly while remaining confident. Conversely, unverified updates risk introducing failures, so regression tests are the guardrails that validate stability at every iteration and build the confidence needed for future change - a need that only grows as applications scale.
Users expect reliability. Regressions are uniquely frustrating because they break something users already trust. Each failure erodes user confidence and damages the provider's credibility. Therefore, a visible regression strategy signals a commitment to quality.
What are the types of regression testing?
"Retest-all" means running the entire test suite after a code change. Because every functional and non-functional case is tested, this approach delivers the highest possible coverage and the strongest assurance that nothing has regressed. The price is significant: full-suite execution consumes substantial time, compute capacity, and staff attention, making it unsuitable for day-to-day updates in an active codebase. Teams therefore reserve retest-all for exceptional events - major releases, architecture overhauls, platform migrations, or any change whose impact cannot be scoped.
Selective regression testing targets only the cases tied to the latest code changes. By skipping unrelated scenarios, it trims execution time and resource use compared with a full-suite run. The trade-off is safety: the approach relies on accurate impact analysis to choose the right subset. If that analysis misses an affected component, a defect can slip through untested. When change mapping is reliable, selective testing delivers a practical balance between speed and coverage. When it is not, the risk of undetected regressions rises sharply.
Test-case prioritization (TCP) rearranges the test suite so the cases with the highest business or technical importance run first. By front-loading these critical tests, teams surface defects sooner and shorten feedback loops. Because code, usage patterns, and risk profiles change over time, the priority order should be reviewed and adjusted regularly. TCP accelerates fault detection but does not trim the suite itself - every test still runs; only the sequence changes.
Regression testing comes in several scopes, each matched to a specific change profile.
Unit regression reruns only the unit tests for the component that changed, confirming the local logic still works.
Partial regression widens the net, exercising the modified code plus the modules it directly interacts with, catching side effects near the change.
Complete (full) regression is the retest-all approach described above: the entire system suite runs, so teams reserve it for large releases or high-risk shifts.
Corrective regression re-executes existing tests after a code change that does not touch the specification - a bug fix, a refactor, an environment or data update - so the established suite can be reused as is.
Progressive regression applies when the specification itself changes. It blends new test cases that cover updated requirements with the established suite, ensuring fresh functionality behaves as specified while legacy behavior remains intact.
What is the difference between retesting and regression testing?
When a defect is fixed, retesting confirms that the specific fault is gone, while regression testing checks that the rest of the application still behaves as expected.
Unit testing vs regression testing
Unit tests focus on single, isolated pieces of code and prove them once. Regression reruns tests at any level - unit, integration, system - after a change to make sure edits in one area have not disrupted another.
Integration testing vs regression testing
Integration tests look at how modules work together, and regression testing reassures the team that those connections continue to hold after new code is merged.
Smoke testing vs regression testing
A smoke test is a quick gate that tells you whether the latest build is even worth deeper investigation, whereas regression digs much further to validate overall stability.
Sanity testing vs regression testing
Sanity tests offer a narrow, post-fix spot-check - regression provides a systematic sweep across key workflows.
Functional testing vs regression testing
New feature functional tests prove that fresh capabilities perform as intended, while regression protects all the established behavior from being broken by those new changes.